
Crawl Readiness MCP Server認証済み注目
@Grubbomatic
基本情報

Crawl Readiness MCP Server について
MCP クライアント向けの AI SEO ツール。AI クローラーがサイトを読めるかを監査し、JSON-LD と robots.txt を検証し、llms.txt、AI クローラー対応の robots.txt、JSON-LD schema を会話を離れずに生成します。
Crawl Readiness MCP Server の設定
以下の設定を使って、このサーバーを MCP 対応クライアントに追加してください。
{
  "mcpServers": {
    "crawl-readiness": {
      "command": "npx",
      "args": [
        "-y",
        "crawl-readiness-mcp"
      ]
    }
  }
}
Crawl Readiness MCP Server のツール
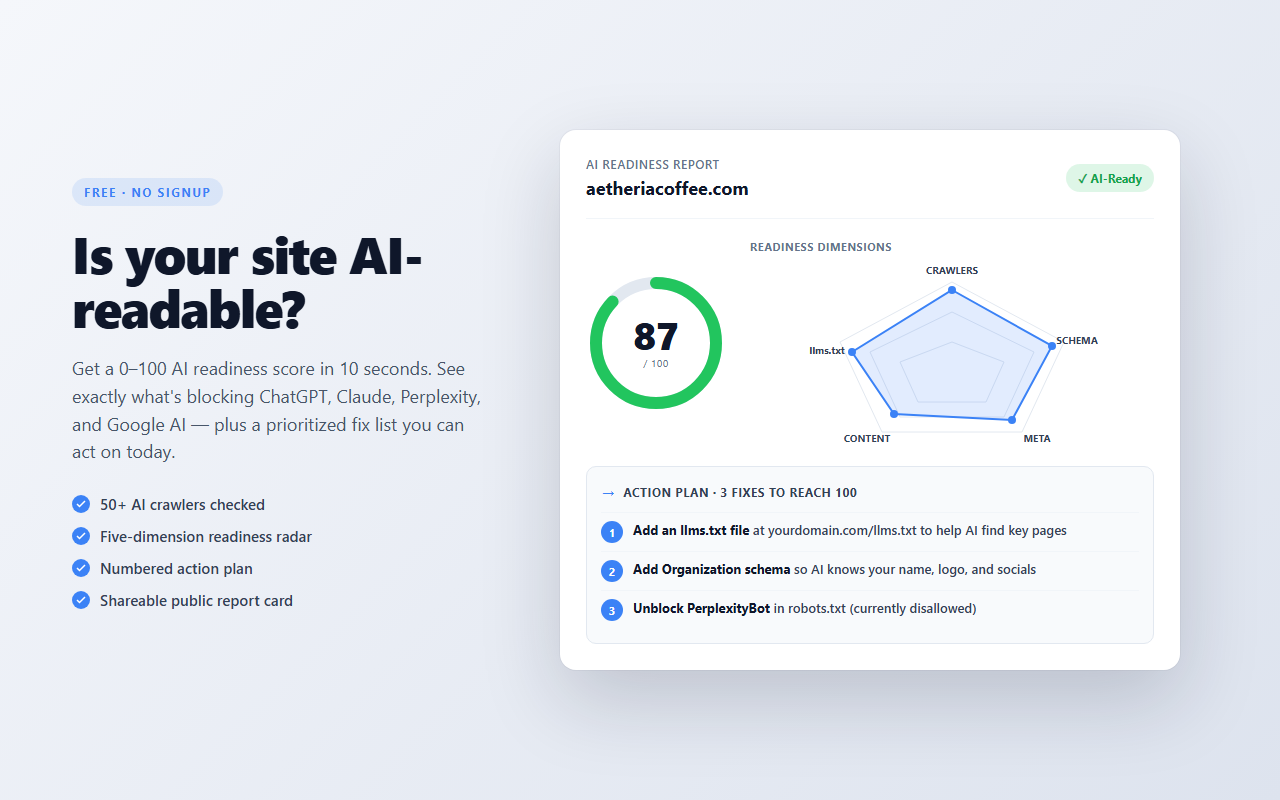
8Check whether AI crawlers (ChatGPT, Claude, Perplexity, Google AI, and 50+ others) can access a website. Returns a 0-100 AI readiness score, per-crawler access status, detected AI-specific files (llms.txt, agents.json), structured data presence, meta signals, and a prioritized fix list. The score counts the crawlers that feed AI search and answers: each entry in `robots.results` carries its `purpose` and whether it is `scored`, and training-only crawlers are listed but never counted, so blocking them does not lower the score. Fixes marked `extra: true` (llms.txt, agents.json, Content-Signal, a markdown copy, agent-ready forms) are informational 'Going further' items and do not affect the score; present them as optional. Use this as the first step in any AI SEO audit.
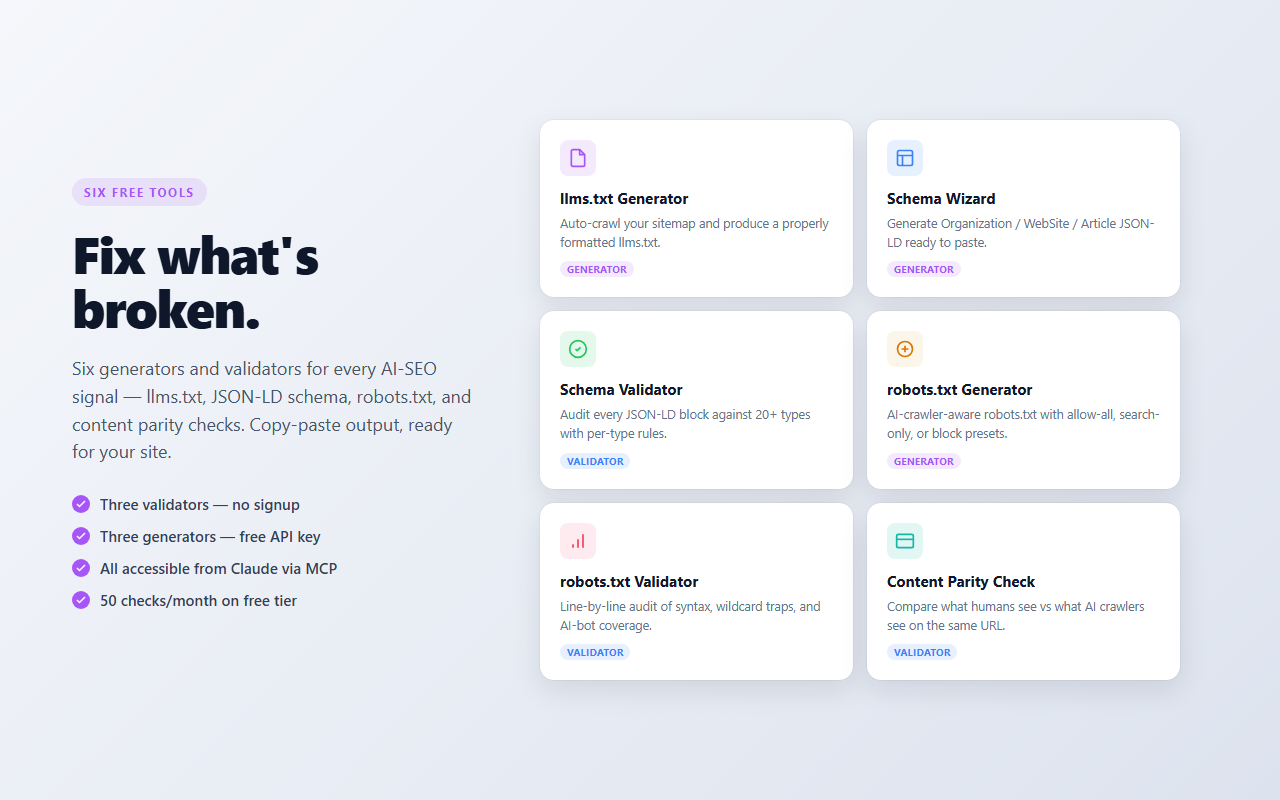
Validate all JSON-LD structured data on a URL. Extracts every <script type="application/ld+json"> block, runs each through a rules engine covering 20+ common types (Article, Organization, Product, LocalBusiness, FAQPage, Recipe, Event, etc.), and reports required-field errors, recommended-field warnings, and type-specific gotchas.
Audit a robots.txt file line-by-line. Detects syntax errors, empty user-agent groups, orphan Allow/Disallow lines, non-slash paths, non-numeric Crawl-delay values, unofficial Noindex usage, and wildcard traps. Also summarizes AI-bot coverage across 50+ known AI crawlers. Provide EITHER url (to fetch and audit) OR text.
Compare what human browsers see vs what AI crawlers see. Fetches a page four times in parallel — as Chrome, GPTBot, ClaudeBot, and PerplexityBot — and reports word-overlap %, title/description differences, and warnings about JS-only shells, cloaking, or edge-based bot blocking.
Generate a properly formatted llms.txt file for a website. Crawls the site's sitemap, groups pages by section, pulls page titles and descriptions, and produces both the llms.txt content and a companion robots.txt snippet. The AI client can then write the returned content to disk in the user's project. Requires an API key.
Generate a complete, ready-to-save AI-crawler-aware robots.txt for a website. Fetches the existing robots.txt (if any) and returns the finished file in `generated.robotsTxt` — the existing rules with an AI-crawler policy section merged in — plus the per-bot allow/block breakdown. Presets: 'allow-all' (every AI crawler allowed), 'recommended' (blocks only the training-only crawlers; everything that feeds AI search and answers stays allowed), 'search-only' (allows only the crawlers that feed AI search and answers, the ones the readiness score counts, and blocks the rest), 'block-all'. A file from 'recommended' or 'search-only' loses no points for crawler access. Write `generated.robotsTxt` to the site's /robots.txt. Requires an API key.
Generate JSON-LD structured data for a website. Detects the site's name, logo, social profiles, contact info, and article metadata, then produces Organization, WebSite, and (when applicable) Article schemas plus starter templates for BreadcrumbList and FAQPage. Returns each schema as a <script type="application/ld+json"> block ready to paste into the site's <head>. Requires an API key.
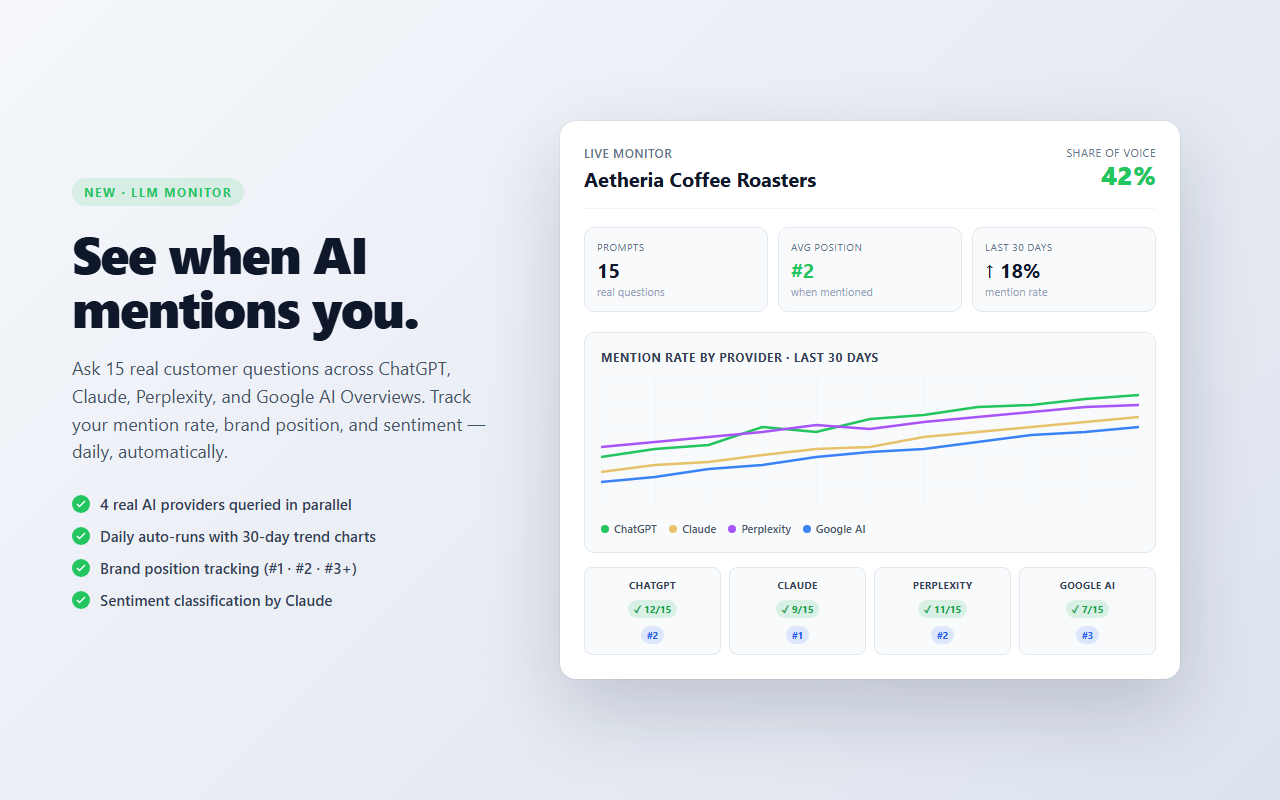
See whether AI assistants (ChatGPT, Claude, Perplexity, Google AI) actually mention a brand in their answers, and how that share-of-voice is trending versus competitors, week over week. Call with NO argument to list the user's monitored brands with each one's current mention rate and direction; pass a brand name or project id to get that brand's full trend, per-provider breakdown, competitor comparison, average position, and short example answers. Reads data the user's LLM Monitor projects have already collected — it does not trigger new runs. Read-only. Requires an API key.
概要
AI SEO tools inside Claude, Cursor, Cline, and other MCP-compatible clients.
Ask your AI "is my site AI-readable?" and it actually checks — running a live audit against 50+ AI crawlers (ChatGPT, Claude, Perplexity, Google AI). Then ask it to fix what's broken, and it can generate a proper llms.txt, robots.txt, or JSON-LD schema and write it into your project.
Install (Claude Desktop)
{
  "mcpServers": {
    "crawl-readiness": {
      "command": "npx",
      "args": ["-y", "crawl-readiness-mcp"]
    }
  }
}
Same shape works for Cursor, Cline, Windsurf, and Continue.
Tools
Audit (no signup):
- check_ai_readiness — 0–100 score against 50+ AI crawlers with a fix list
- validate_schema — JSON-LD audit (20+ types)
- validate_robots — line-by-line robots.txt audit
- check_content_parity — human vs AI-crawler view diff
Generate (free API key at crawlreadiness.com/dashboard):
- generate_llms_txt — auto-crawl a site and produce llms.txt
- generate_robots_txt — AI-crawler-aware robots.txt with presets
- generate_schema — Organization / WebSite / Article JSON-LD
MIT licensed. Full docs at crawlreadiness.com/mcp.
「開発者ツール」の他のコンテンツ
Ramen
bkraad47Multi-zone MCP server for GKE/EKS/AKS: Python tools from git, NeMo guardrails, SSO, autoscaling.

LocalCan
LocalCanGives AI agents public URLs (tunnels) for localhost, live HTTP traffic inspection, snapshot publishing, and access control. Part of LocalCan, the ngrok alternative for Mac, Windows and Linux. Free plan.

Mobbin
MobbinMobbin MCP connects your AI agents to 600,000+ real product screens, so what they build starts with what already works.

FARPY
mangomunchrVerified distributed compute for humans, applications, and agents. Submit Blender, Octane, and video workloads, route them across qualified GPUs, track asynchronous execution, download finished artifacts, and verify FARP
Moxie Docs
Jackalope-DevAutomated codebase documentation for GitHub: searchable docs, MCP context for AI agents, doc drift detection, and Friday Cleanup PRs.
コメント